Memory Leak Hunting with MemLab
- Published on
- 9 min read
Table of contents
- Background
- A 40MB Surprise
- Why bother
- How I scaled the manual labor
- MemLab
- Traces name classes (not causes)
- The loop: AI assistant + self-verification
- The numbers
- Update (as of the end of my internship)
- Three takeaways
Background
Some observant of you may have observed that I have interned in the same workplace (OnSquare in Seoul) once again this year. It was rather a good chance to see whether I myself have improved over the last 2 years (since the last internship there was in 2024). This blog post describes one of the contributions I have made throughout my internship this year.
A 40MB Surprise
I was clicking around the Memory and Performance tabs of Chrome DevTools out of curiosity, on a big single-page app I work on — Looina. Looina has a section where you can use a canvas-based visual editor - the kind of page that stays open in a tab all day without being reloaded (like Figma, Canva, Excalidraw).
I wanted to see what the Memory tab does. So I took a heap snapshot on the home screen: about 160MB. Opened one other page, did something with it, navigated back, took another snapshot: about 200MB.
40MB memory increase, from one interaction! And it never came back after leaving the page. That smelled like a leak to me...
Why bother
Plenty of web apps get away with sloppy memory cleanup because the page reloads constantly — every route change is a fresh document, and whatever was left behind gets thrown out with the old one. A long-session editor doesn't have that free pass. Editor page keeps its DOM and its JS heap alive for as long as the tab is open, because reloading would throw away the user's in-progress work (imagine designing a logo for half a day and losing it due to some auto-refresh of your browser). So every leaked memory content stacks on top of the previous one, for hours, for days (so long as you keep the tab open without reloading).
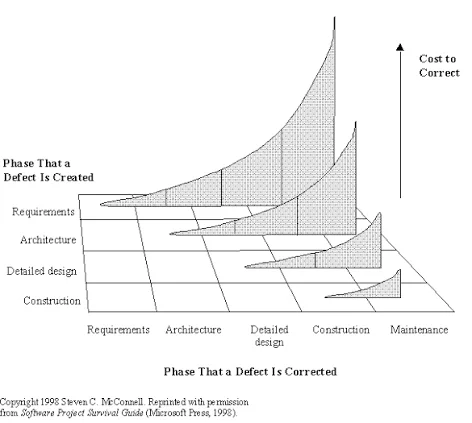
Steve McConnell makes the point in Software Project Survival Guide book: the cost of fixing a defect grows with how long it sits undiscovered, because more and more code gets built on top of the broken pattern. The project Looina was already big. If it doubles again before someone notices the leaks, the fix costs multiples of what it costs today.
How I scaled the manual labor
My 40MB number came from one interaction, tested by my hand, once. Good enough to prove there's a problem for me but useless as a verification strategy. The app has dozens of meaningfully different interactions reachable from the main dashboard alone, and "open DevTools, snapshot, click around, snapshot, eyeball the diff" is not something I was going to repeat dozens of times — let alone re-repeat after every attempted fix.
I needed the same test — snapshot, interact, go back, snapshot, diff — scripted and repeatable.
MemLab
The search for a solution ended at MemLab, Facebook's open-source memory-leak detector. It drives a headless browser through a scripted interaction, snapshots the heap along the way, and reports what stayed retained after navigating back — the same manual test I'd just done, minus the manual part.
I wrote scenarios for 37 distinct interactions in Looina, all directly reachable from the app's main dashboard, plus a small runner script to execute them as one batch and collect the results. (That was still not a full coverage — there are more interaction types buried in sub-pages — but 37 was a varied enough slice to take seriously.)
The measurement I came up with is more careful than my manual test was. MemLab doesn't take two snapshots, it takes five:
for each scenario (repeated 3 times):
    snapshot()   # 1. baseline, on the dashboard
    action()
    snapshot()   # 2. after the interaction
    back()
    snapshot()   # 3. back on the dashboard (ideally same as 1)
    action()
    snapshot()   # 4. after the interaction, again
    back()
    snapshot()   # 5. final, on the dashboard (ideally same as 3)

    leak = final - baseline
The first action/back round absorbs one-time setup costs — caches getting filled, modules getting lazily loaded — so those don't get counted as leaks. Only memory that's still climbing on the second round counts. On top of that I ran every scenario 3 times: enough repetition to rule out random noise, while keeping the full batch runtime realistic (so that I don't have to wait a whole day for my very reliable test to finish).
MemLab reported ~12MB for the interaction my manual test measured at ~40MB. A headless scripted browser isn't a human session — timing, idle cycles, paint behavior all differ — so the absolute numbers disagree. But I had walked through all 37 scenarios by hand before automating them, and the flows MemLab flagged as leaking were the same ones I'd seen leak manually. So I had a confirmation my measurement tool is actually working.
Traces name classes (not causes)
MemLab's output (memlab find-leaks, memlab trace, and its friends) tells you which scenario leaked, how much, and which objects are still being retained. Useful — yet not enough. The objects in those traces were common building blocks used all over the system. When the same class is created and cleaned up correctly in a hundred places, a trace saying "an instance of this class leaked" doesn't tell you which of the hundred places forgot the cleanup, or why.
Each flagged leak needed its own investigation to get from what leaked to why.
The loop: AI assistant + self-verification
I worked through the leaks one by one with Claude Code. Two setup investments made that work:
A tracking spreadsheet. Took me about half a day to build: baseline and leak size, per scenario, per run. Then I duplicated the worksheet each day and labelled the copy with the date, so improvement is a visible day-over-day trend instead of a number I vaguely remember.
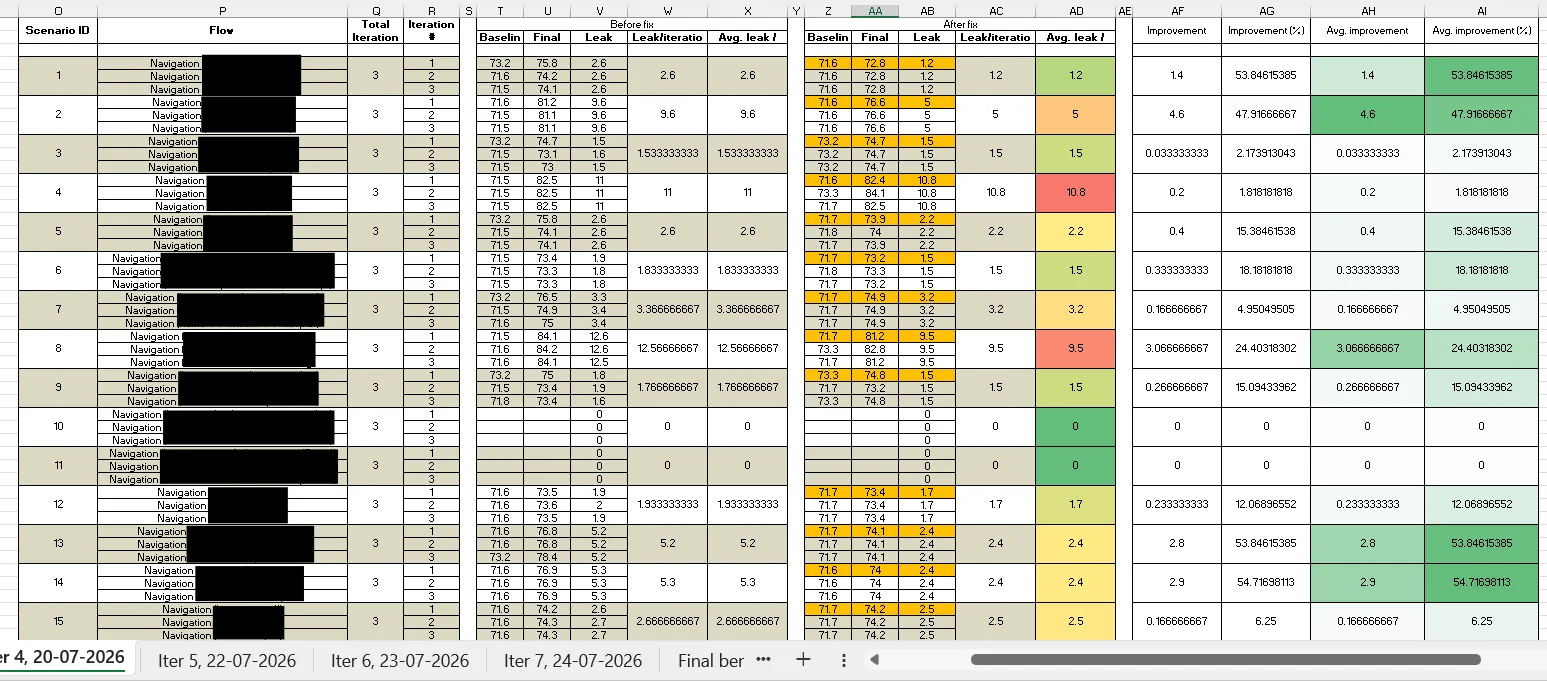
Letting the assistant run MemLab itself. I customized the runner script so the AI assistant could re-run it after each fix and read the fresh output directly. It could verify its own fix against real measurements instead of asserting that the change "most definitely works this time" — and I could stop being the manual verification step in AI's autonomous loop. Cheap to set up, and I think this is the actually valuable skill in the AI era: not prompting in a very sophisticated way each time, but giving the assistant a feedback loop it can close on its own.
With that in place I went after the worst offenders first, starting from the 12MB and 5MB scenarios. Both ended up cut roughly in half — down to about 6MB and 2.5MB — through root-cause fixes, not symptom patches.
The numbers
Across the 35 scenarios that produced a measurable signal (2 of the 37 never showed a delta and were set aside), combined leaked memory went:
- 132.5MB difference baseline → 96.5MB now
- ~36MB difference reclaimed
- ~27% reduction in memory difference, in two days of iterating
Update (as of the end of my internship)
The numbers given above were just the beginning (after trying out the setup I have implemented for 2 work days). But the setup turned out to be very effective in the later days - I could just tell Claude the next page to optimize and let it work on its own while I do some other task myself (instead of resting, yeah, this is South Korea). The final numbers are:
- 132.5MB difference baseline → 71.7MB
- 45.2MB leak baseline → 14.6MB
- ~60.8MB difference and 30.6MB leak reclaimed
- ~68% reduction in memory leak
Again, some observant of you may have observed that I've differentiated memory leak from measured memory difference in the final part - that's because I've figured out a way to do that later after initial two days.
Three takeaways
- You can't fix what you can't measure.
I'll admit the half day on the spreadsheet felt like procrastination while I was doing it — there were actual leaks sitting right there, and I was formatting cells. But it's the only reason I can write "~68% improvement" in this post and mean it. Without the baseline recorded, every fix would have been "seems better?", and I know from experience how that goes: you fix three things, memory still climbs, and now you can't tell whether your fixes did nothing or whether you fixed three leaks and a fourth one is hiding the improvement. The spreadsheet plus the runner script turned every fix into a yes-or-no question with a number attached. Everything else in this post came out of that.
- Working with an AI assistant is a skill.
Here's what it looks like in practice: before I customized the runner script, the assistant would make a change, explain very convincingly why the leak was now fixed, and be wrong about it often enough that I was re-running MemLab by hand after every change — I had become the verification step in my own assistant's loop, which is backwards. After the customization, it re-ran the scenarios itself, read the fresh traces, saw its fix hadn't moved the number, and kept digging without me in the middle. The difference wasn't the AI — it was whether I'd given it a way to know when it was wrong. If you can't set that up, an AI assistant doesn't add to your productivity; it subtracts, with its very high confidence.
- Let yourself have fun.
Nobody asked me to look into memory. No ticket, no bug report, no user complaint — the concern didn't exist until I went poking around DevTools tabs you don't normally open, just to see what they'd show me about my own app. That curiosity is the entire reason this post exists and there've been 68% improvement (which would otherwise have costed some good deal of effort if discovered after product adoption). The counterfactual isn't "someone finds it eventually, no harm done": the project is already big, and by McConnell's cost curve these leaks would have been found at their most expensive — after another term of features built on top of the same broken teardown patterns, probably prompted by users complaining about a sluggish app instead of a quiet afternoon of poking around. An hour of undirected curiosity turned out to be worth more than most planned hours that week. I'm taking that as permission to keep playing.